How the engines decide who to cite, and how much is actually known.
Some of this is documented by the companies themselves. Some is inferred from watching thousands of answers. Some citation advice is guesswork being sold as fact. This page separates the three.

Sources
Key takeaways: how engines decide who to cite
- Do the engines publish how they choose sources? Partly. Google documents what makes a site eligible for AI features and says there is no separate ranking system for them. The others describe their retrieval in general terms and publish no selection criteria.
- What is the one thing they share? They retrieve before they generate, a pattern known as retrieval-augmented generation, or RAG. Each one searches an index, pulls a handful of pages and writes from those, so being in the index being searched is the first requirement.
- Which index does each one use? Google’s AI features use Google’s own. ChatGPT’s web results draw on Bing, among other providers. Copilot is Bing. Perplexity runs its own crawler alongside third-party sources.
- What is still unknown? The weighting. Nobody outside these companies knows how much brand mentions, freshness, schema or domain history each count for, and anyone quoting you a percentage is estimating.

What do all four engines have in common?
They retrieve before they generate. Each one runs a search against an index, pulls a small set of pages, and writes an answer from what it pulled. The model is not recalling your website from training. It is reading it at the moment of the question.
Researchers call this pattern retrieval-augmented generation, or RAG. The term comes from a 2020 research paper describing models that combine what they learned in training with documents they look up. For a website owner the practical meaning is short: your page has to be found first, and then it has to be easy to quote.
That single fact decides most of the practical work. If your pages are not in the index being searched, nothing about your writing matters. If they are in it, but the answer is buried in paragraph four, the engine summarizes someone whose answer was in paragraph one.
A page that is never retrieved cannot earn a citation. Engines cite what they can find and read.
Which index does each engine search?
Google AI Overviews and Gemini search Google's own index. Copilot searches Bing. ChatGPT draws on Bing, among other providers. Perplexity uses its own crawler alongside third-party search sources. This is the layer worth acting on, because whether your pages are in each index is a fact that can be checked, not a guess.
Being in the right index comes before any citation. An engine cannot cite a page its index has never seen.
| Engine | Where its web results come from | What that means for you |
|---|---|---|
| Google AI Overviews and Gemini | Google’s own index. | Your Google ranking and indexing work carries straight over. See AI Overviews. |
| ChatGPT | Bing, among other search providers. | Bing Webmaster Tools verification and a submitted sitemap are the entry ticket. See ChatGPT SEO. |
| Copilot | Bing. | Same work as ChatGPT, with Microsoft’s own surfaces on top. See Copilot and Bing. |
| Perplexity | Its own crawler, alongside third-party search sources. | Make sure your robots.txt is not blocking crawlers you meant to allow. See Perplexity SEO. |
This is the layer worth acting on, because it is verifiable. We confirm every page is indexed in Google and in Bing as part of each build and uplift.
What is documented, and by whom?
Google publishes guidance for its AI features in Search. The part worth reading twice is that there is no separate set of ranking signals for them: the same work that makes a page eligible for ordinary results makes it eligible here. Google asks for unique, satisfying content, working technical basics, and markup that reflects the page.
The others publish far less. OpenAI, Microsoft and Perplexity document how their crawlers identify themselves and how to allow or block them, which is operationally useful and says nothing about selection. None of them publishes criteria for which of ten retrieved pages gets named.
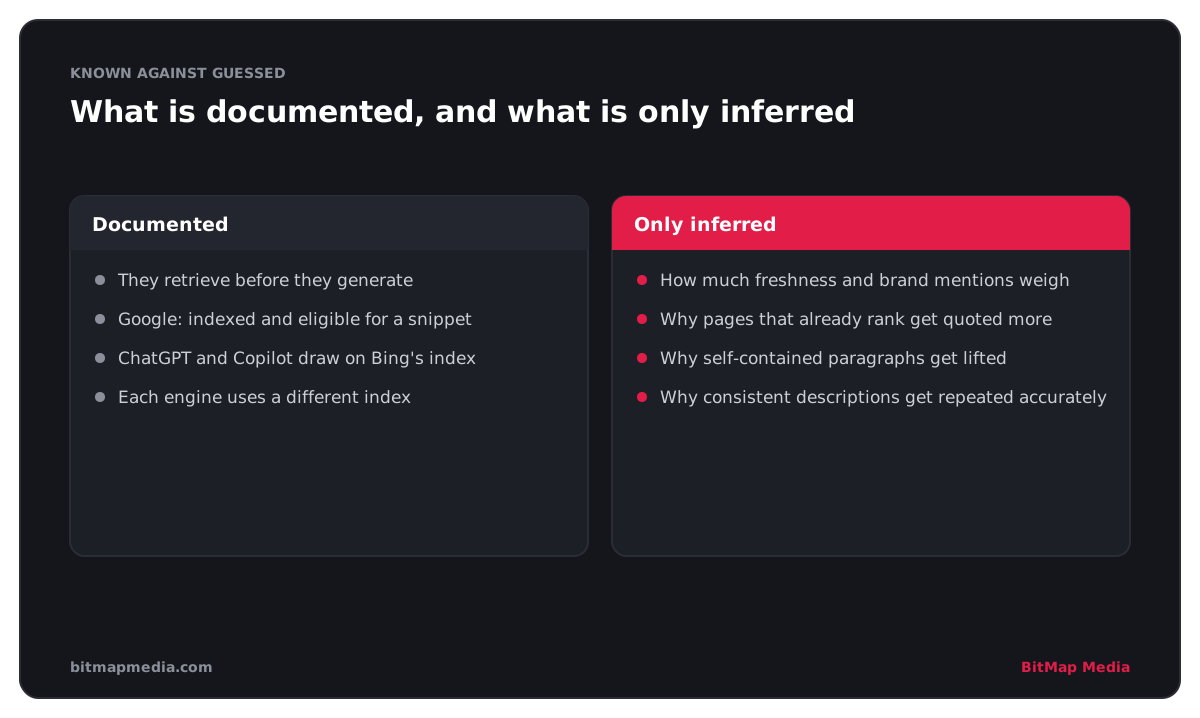
So the honest state of knowledge is: the eligibility layer is documented, the selection layer is not.
Nothing in that guidance promises a citation.
What is only inferred
These are patterns many people have observed, including us, which no engine has confirmed. We act on them because they are cheap and consistent with the documented layer, and we label them as inference, not fact.
We treat these as likely citation signals, not as rules. No engine has said these patterns decide who it will cite.
- Pages that already rank well are quoted more often than pages that do not. Consistent with retrieval-then-generation, and with Google saying its AI features use the same systems.
- Self-contained paragraphs get quoted more than paragraphs that depend on the one above them. This is what you would expect of any extraction step.
- A business described the same way across the web gets described more accurately than one described six different ways. See NAP consistency.
- Pages with accurate structured data do not automatically win, but pages whose markup contradicts their visible text seem to do worse.
What nobody outside these companies knows is the weighting. If you are shown a figure for how much any single factor counts, ask how it was measured. Usually it is a correlation across a sample of answers, which is interesting and is not the same thing.
What we do with the uncertainty
We work the documented layer hard and treat the rest as probability. Rank the page, get it indexed in Google and Bing, put the answer first, name the entities, keep the schema honest. Every one of those helps under any weighting, and none of them is wasted if the systems change.
We also tell you when a result is only a sample and not a measurement. Ask an assistant the same question twice, and you may get two different source lists, so a single screenshot proves very little. That is why our free score reports what it read on your pages, does not claim a position in a system we cannot see, and marks anything it could not measure as not measured.
That is the honest way to work toward a citation. Nobody can promise a citation, and we do not.
What do the statistics say about how AI engines pick sources?
Pew Research Center found Wikipedia, YouTube and Reddit were the most linked sources in Google's AI summaries. A 2024 study found that cited, quoted and statistic-rich content gained visibility in AI answers.
Statistics last updated 10-30-2026. Each figure links to the organization that first published it.
- Wikipedia, YouTube and Reddit were the most commonly linked sources in both Google AI summaries and standard results in Pew Research Center's March 2025 study. Source: Pew Research Center, 2025.
- Wikipedia, YouTube and Reddit together made up 15% of the sources listed in Google AI summaries and 17% of the sources in standard results in Pew Research Center's March 2025 study. Source: Pew Research Center, 2025.
- Generative engine optimization methods can raise a source's visibility in generative engine answers by up to 40%, according to the GEO study by Aggarwal et al. (KDD 2024). Source: Aggarwal et al., 2024.
- In the GEO study by Aggarwal et al. (KDD 2024), citing sources, adding quotations and adding statistics each improved visibility by 30-40% on the Position-Adjusted Word Count measure. Source: Aggarwal et al., 2024.
- Keyword stuffing gave little to no improvement in generative engine answers in the GEO study by Aggarwal et al. (KDD 2024). Source: Aggarwal et al., 2024.
Questions about citation
What is RAG, and why does it matter for my website?
RAG, short for retrieval-augmented generation, means an AI looks up pages first and then writes its answer from them. For your site, that means being indexed and easy to quote matters more than clever wording.
Can I pay to be cited?
Not in the organic citations. Paid placements inside AI products exist and are labeled as ads where they appear. Anyone offering to get your brand into the organic answer for a fee is either describing ordinary optimization work or selling something that does not exist.
Why does one assistant name me and another does not?
Usually the index. A site well indexed in Google and thinly indexed in Bing will show up in AI Overviews and not in ChatGPT, which is the single most common split we see. Checking site: counts in both engines takes two minutes and explains most cases.
Does being cited once mean I will be cited again?
No. Ask the same question twice, and you can get different sources, because these systems retrieve fresh each time and some of them personalize by location and account. Treat any single result as one sample, not a ranking.
Do brand mentions on other sites help?
They appear to matter, and that is an honest “appear”. A model that has seen your business described consistently across the web has more to draw on than one that has only seen your own site. How much weight it carries is not documented by anyone.
Is there a tool that tracks my citations?
Several expensive paid tools exist, and the thing to understand before buying one is that they all work by asking the engines questions and recording the answers. The value is in doing it consistently against the same question set, not in any privileged access. We use several paid tools to do this work for our clients.
What do you do about all this uncertainty?
We work the parts that are documented and reliable: ranking, indexing in both engines, answering the question in the first paragraph, naming your entities, keeping your schema accurate. Those hold up whatever the weighting turns out to be. We skip anything whose only justification is a confident claim about a system nobody outside the company can see.
Marketers with decades across print, TV, direct mail, email, web, video and CRM. Updated 10-30-2026. About the team
Find out whether the engines can read your pages at all.
Before worrying about weighting, check the parts that are documented. The free AI Visibility Score reports eight of them on your own site.
Get your Free AI Visibility ScoreRelated pages
All Knowledge Base guides
- 15 Questions to Ask Before You Hire an Agency
- AI-Ready Website: The Eight Points We Check
- Entity Pages: How a Machine Confirms Your Business
- Getting Reviews Without Gaming Them
- Google Business Profile: The Fields That Do the Work
- How to Read Your Google Search Console
- llms.txt Explained: What Is Known and What Is Hype
- Map Pack Answers: 5 Clear Wins in AI Search
- Map Pack: Relevance, Distance and Prominence Explained
- Master FAQ Page: How to Build One That Gets Quoted
- NAP Consistency: Why Small Differences Cost
- Schema for Service Businesses: The Types That Matter
- SEO, AEO, GEO and AIO Explained
- What a Website Care Plan Should Include
- Who Owns Your Website? 6 Things to Check Today
- AI Citation Kit